


1 hour
A GPU That Never Sleeps Costs $584 to $2,913 a Month. The API Sells the Same Month for a Fraction, Until You Pass a Billion Tokens
What this is for
For a developer whose scripts call an API and who wants to know what running an open model themselves costs. You get a private endpoint live in about ten minutes, billed by the GPU minute, and the break-even against the API price for your volume.
What you make
A private HTTPS endpoint serving an open-weight model of your choice, live within ten minutes, that your scripts call like an API and that you stop at the end of the day.
CHECKED 2026-09-1416 SOURCES20 NUMBERSUPDATED 2026-09-16
Typical earnings
Nothing from hosting; the cost line changes
Startup cost
$0 account; GPU from $0.50 an hour
Time to first payout
Endpoint live in 3 to 10 minutes
Difficulty
4/5
Why this pays
A small team wants an open model of its own: a private endpoint its scripts call the way they call an API, running weights it chose, on a GPU it rents by the minute and switches off at six. The question is not whether it can be done, it can, in ten minutes, but whether the GPU month beats the API month, and both numbers are printed.
| The same capacity, two ways | |
|---|---|
| A working day, eight hours, on Hugging Face's recommended Nvidia L4 at $0.8 an hour | $6.40 |
| A month, 730 hours, on that L4 | $584 |
| A month on Together's on-demand H100 at $3.99 an hour | $2,913 |
| What $2,913 buys on Mistral Large's API at $1.5 per million output tokens | about 1.9 billion tokens |
| Together's serverless DeepSeek V4 Flash, per million tokens | $0.14 in, $0.28 out |
An idle GPU costs the same per minute as a busy one until it is scaled to zero. A team that will not push a billion tokens a month, and does not need the model, the data or the latency on one machine, is paying for an empty GPU. A team that does, or runs a fine-tune no API serves, has its answer in the other column.
The play, in three lines
- Read the licence on the weights, then deploy from Hugging Face's Inference Endpoints Catalog with the defaults, or with one
tg beta endpoints deploycommand on Together. - Point your code at the Endpoint URL with the same chat request it already sends, run the day's job, and read the minutes on the billing page.
- Stop it before you leave, check which idle clock your endpoint actually uses, and put your real monthly token volume next to $584 and $2,913.
The path above walks every step. What follows is the reasoning behind each and the numbers you quote from.
Where the money comes from
- Nowhere, directly. This is a cost line that changes shape: from per token to per GPU minute.
- The saving, at volume. Past about a billion output tokens a month at Mistral Large's rate, the on-demand H100 is cheaper than the API; below it, the API is.
- What no API sells. A fine-tune of your own, data that cannot leave one machine, latency you control. Those have no token price to compare against.
The pain you are selling the cure for
The team's scripts already work against a hosted API, and three things itch: the bill grows with every call, the data goes to someone else's server, and the model can change under them. The endpoint fixes all three for the price of a GPU that never sleeps, which is why the whole page turns on stopping it.
The path, step by step
Every figure below is read from the platform profile it belongs to, not written into this page. Follow a name to see every answer we have for that platform.
- 1Read the licence on the weights before you rent anything
Mistral's open-weight models are Apache 2.0 for research and individual use, and commercial deployments require a Mistral license with separate terms. Every model card on Hugging Face carries its own licence line. The GPU price is the same whatever you run on it; the licence is what decides whether you may sell what comes out.
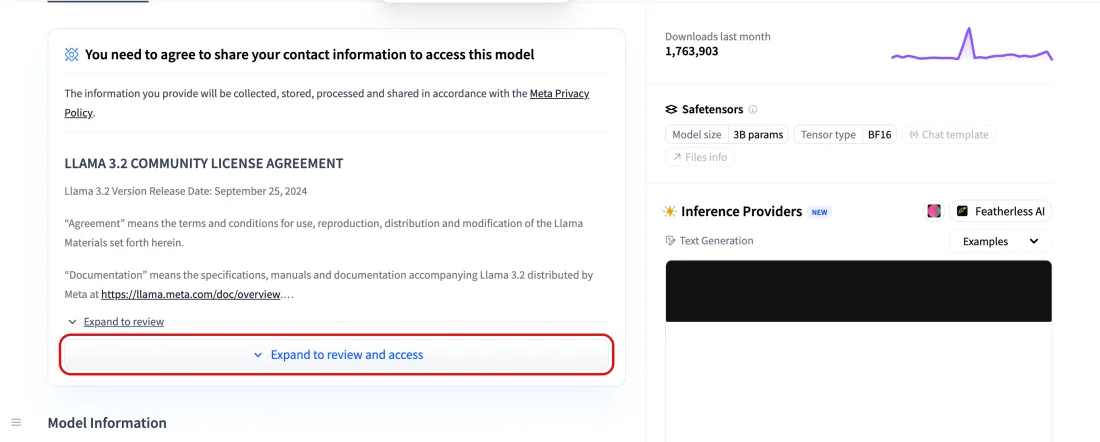
Outlined in red: Expand to review and access
. Model card of a gated model: the contact-sharing notice and the licence text that must be accepted before the weights can be pulled, Hugging Face, screenshot taken 2026-09-16. Account details are masked.Who owns what you buildMistral AIOpen-weight models are Apache 2.0 licensed for research and individual use, while commercial deployments require a Mistral license with separate terms for derivatives and production usesource · checked 2026-09-11Hugging FaceYou own the Content you create; Hugging Face will not sell it, though posting it grants the license the Terms describe, and it may remove your Content at any time at its sole discretion if it has a concern about itsource · checked 2026-09-12 - 2Path A, in the browser: Hugging Face Inference Endpoints from the Catalog
Put a card on file in billing settings first. In the Inference Endpoints UI click Catalog, search the model (the quick start uses Llama 3.2 3B Instruct), open its card and keep the pre-selected hardware; the catalog recipe for that model runs on one L40S at $1.80 an hour (the older quick start named an L4 at $0.80). Click Create Endpoint and wait 3 to 5 minutes. The Overview tab shows the Endpoint URL; the Playground tab lets you chat with it and copy the code snippet with your token. Endpoints are private by default.
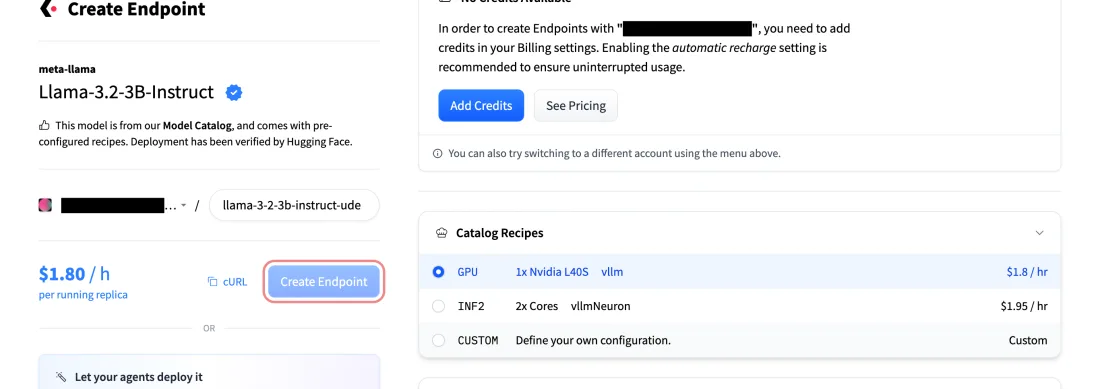
Outlined in red: Create Endpoint
. Inference Endpoints, Create Endpoint for a Catalog model: the hourly price per running replica, the pre-selected GPU recipe and the No Credits notice that blocks the button until billing is set up, Hugging Face, screenshot taken 2026-09-16. Account details are masked.What it really costs to startHugging FaceFree: a free account, a CPU Basic Space with 2 vCPU and 16 GB is FREE, and Spaces hardware starts at $0; PRO is $9 /month if you want more storage, inference credits and ZeroGPU quotasource · checked 2026-09-12 - 3Path B, one command: a Together dedicated endpoint
With the Together CLI installed and an API key set, tg beta endpoints deploy google/gemma-4-E4B-it --endpoint quickstart-endpoint creates the endpoint and a deployment on the model's default hardware and prints an endpoint string; provisioning takes about 5 to 10 minutes while the weights download. The console does the same from Endpoints, New endpoint, with a model, hardware, region and min and max replicas.
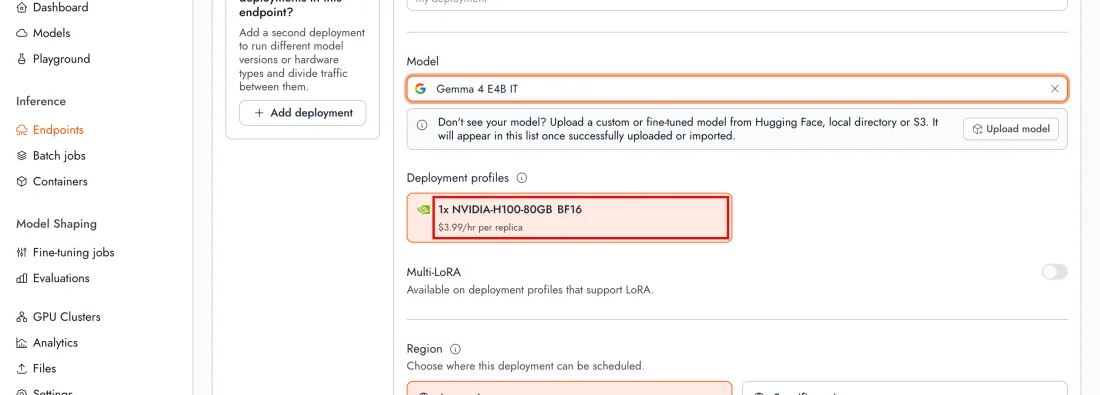
Outlined in red: 1x NVIDIA-H100-80GB BF16
. Endpoints, New endpoint: the model picked and the deployment profile it runs on, with the price per replica per hour, Together AI, screenshot taken 2026-09-16. Account details are masked. - 4Point your tools at it with the same request shape
On Together, set the base URL to api-inference.together.ai/v1 and pass the endpoint string as the model parameter to the ordinary chat completions call; nothing else in your code changes between serverless and dedicated. On Hugging Face, the Playground's API section gives the snippet for the Endpoint URL with your token. Run the day's job.
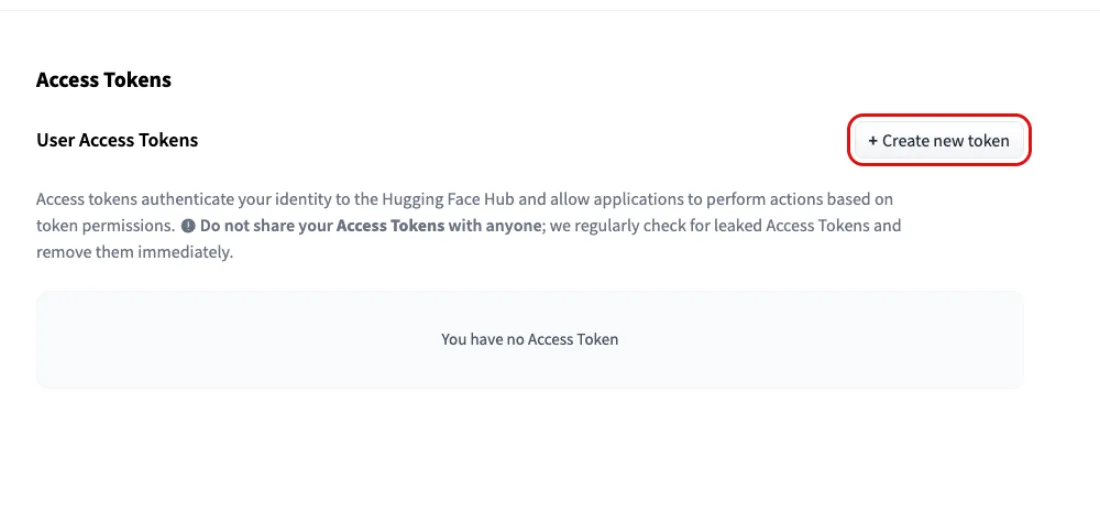
Outlined in red: Create new token
. Settings, Access Tokens: the empty list and the button that makes the token your code sends with every request, Hugging Face, screenshot taken 2026-09-16. Account details are masked. - 5Price the day by the minute, and the month by 730
Inference Endpoints show hourly rates and bill by the minute: T4 $0.5, L4 $0.8, A10G $1, A100 $2.5, H200 $5. Eight hours on an L4 is $6.40; 730 hours is $584. Together's on-demand H100 is $3.99 an hour, $1.99 preemptible; fal's H100 is $1.89. Multiply by 730 before you compare anything to an API price.
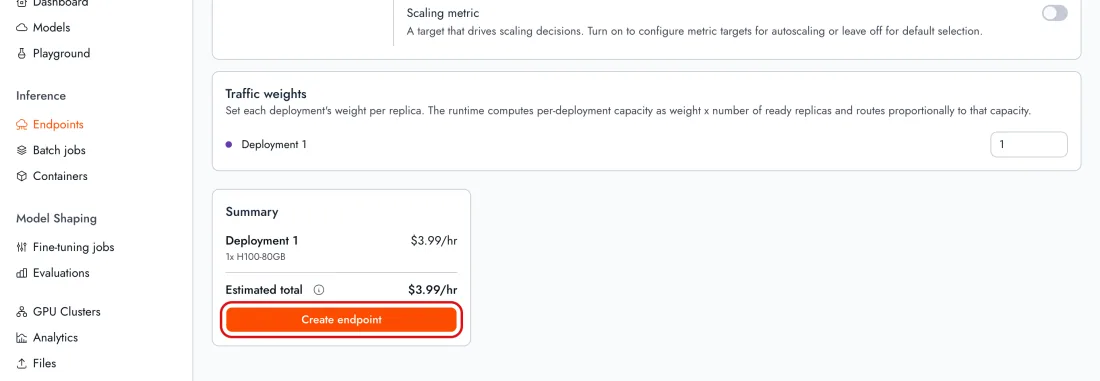
Outlined in red: Estimated total
. New endpoint, Summary: the estimated hourly total for one replica, the number the day and the month are priced from, Together AI, screenshot taken 2026-09-16. Account details are masked.What it costs to keep aliveHugging FacePRO $9 /month, Team $20 /month per user; on-demand hardware by the hour, from $0.03 for a CPU Upgrade and $0.40 for a small Nvidia T4 up to $20.00 for 8x A100; dedicated Inference Endpoints from $0.033/hoursource · checked 2026-09-12Together AIPer 1M tokens: DeepSeek V4 Flash $0.14 in and $0.28 out, MiniMax M3 $0.30 in and $1.20 out, Kimi K3 $3.00 in and $15.00 out; GPUs per hour on demand, NVIDIA HGX H100 $3.99 or $1.99 preemptible, H200 $5.99, B200 $8.99source · checked 2026-09-12 - 6Put the API price next to it, in tokens
Mistral Large output is $1.5 per million tokens, so the $2,913 an on-demand H100 costs for a month buys about 1.9 billion output tokens at the API. Together's serverless DeepSeek V4 Flash is $0.28 per million out. Unless the team will actually push that volume, or needs the model, the data or the latency to stay in one place, the API wins on cost.
- 7Stop it before you leave; idle costs the same as busy until it is at zero
On Together, Stop scales the deployment to zero replicas and releases the hardware; in the STOPPED state it is neither billing nor serving, and Start brings it back. On Hugging Face, scale-to-zero is on by default and the endpoint can be paused; a cold start after zero returns 502 until the replica is up, and there is no queue. The two Hugging Face pages disagree on how long idle lasts before zero: 1 hour on one, 15 minutes on the other.
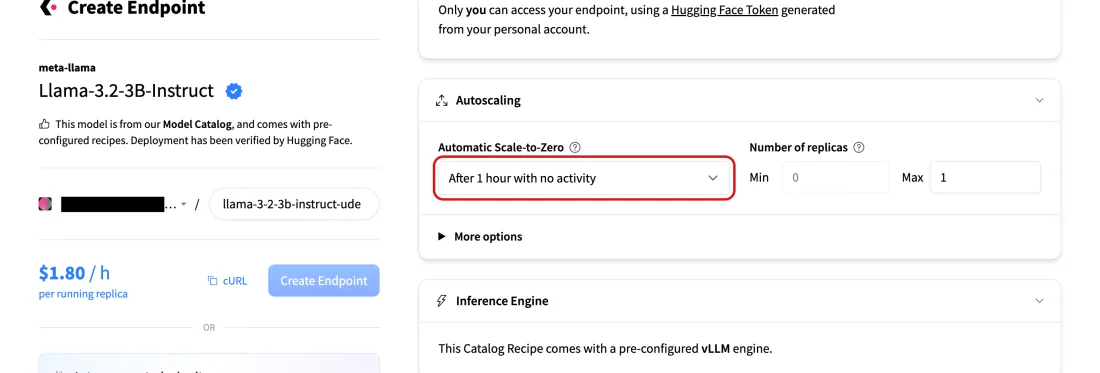
Outlined in red: Automatic Scale-to-Zero
. Create Endpoint, Autoscaling block: the idle timer that takes the endpoint to zero replicas, where it stops billing, Hugging Face, screenshot taken 2026-09-16. Account details are masked. - 8Read the clauses that bite a small team
Together's credits funded by ACH or wire are not usable until they clear, and access can be suspended if any amount is 5 days past due. Hetzner's listed prices are net and German customers pay 19% VAT on top. Fund by card if the first job is this week.
The gate before it pays anythingTogether AIPay as you go, with fees that are non-refundable; credits funded by ACH or wire are not usable until the payment clears, and access can be suspended on notice if any amount is 5 days past duesource · checked 2026-09-12HetznerNot checked yet - 9Check what leaves with you
Mistral's open weights can be self-hosted anywhere. Hugging Face says you own the Content you create. DigitalOcean's snapshots and backups cannot be downloaded off the platform; getting data out means copying it yourself. Keep the weights, the prompts and your data somewhere you can download from.
Can you take it with youMistral AIYes, you can self-host the open-weight models anywhere, so a workflow built on them does not depend on the hosted API staying available at the same pricesource · checked 2026-09-11Hugging FaceYou may cancel your Account whenever you want, at your sole discretion; open models and datasets you host are files you can pull down, and a paid plan is a limited right to access a Service, not ownership of itsource · checked 2026-09-12DigitalOceanSnapshots and backups cannot be downloaded off the platform. Getting data out means copying it yourself with third-party tools such as rsync or SFTP.source · checked 2026-09-07 - 10Read what ends it, on both the host and the hub
Hugging Face may suspend or terminate access at any time, with or without cause or notice, and may remove Content at its sole discretion. Together's agreement cannot be terminated by you without its written consent. DigitalOcean can terminate access effective immediately and deletes Services Content on termination.
What takes it all awayHugging FaceHugging Face reserves the right to suspend or terminate your access to the Services anytime with or without cause, at its own discretion, with or without notice, and may modify, suspend or discontinue the Services or any part of themsource · checked 2026-09-12Together AITogether may suspend access or terminate the Agreement if it determines you breached it, needs to prevent a credible risk of harm or liability, or is required by law, taking reasonable steps to give written notice first; you may not terminate without its written consentsource · checked 2026-09-12DigitalOceanDigitalOcean can terminate access at any time, with or without notice, effective immediately, and owes you nothing back: it deletes Services Content on termination under its standard closure practice.source · checked 2026-09-07
Check these five before you sign up
- Read the model's licence first: Mistral's open weights are Apache 2.0 for research and individual use, and commercial deployments require a Mistral license with separate terms.
- Put a card on file, then deploy from the Catalog with the defaults; the endpoint is live in 3 to 5 minutes on Hugging Face, 5 to 10 on Together. Keep it private and pass the token.
- Multiply the hourly GPU price by 730 before you compare it to anything. One on-demand H100 at Together is $3.99 an hour, about $2,900 a month; preemptible is $1.99; fal is $1.89; a Hugging Face L4 is $0.8, about $584.
- Convert the API price to the same month: Mistral Large output is $1.5 per million tokens, so $2,900 buys about 1.9 billion output tokens. If the team will not use that, the API wins on cost.
- Stop or scale to zero before you leave. Both hosts bill by the minute while a replica runs; a stopped Together deployment and a zero-replica Hugging Face endpoint bill nothing.
- Check your own endpoint's Settings for the idle period; Hugging Face's two pages say 1 hour and 15 minutes.
- Fund Together by card if the first job is this week: ACH and wire credits are not usable until they clear, and access is suspended if anything is 5 days past due.
- Keep the weights and your data somewhere you can download from. DigitalOcean's snapshots cannot be downloaded off the platform, and Hetzner puts backups on the customer.
HUGGING FACE PUBLISHES THIS TWO WAYS
How long an idle Hugging Face Inference Endpoint waits before scaling to zero
15 minutes
Two pages of the same documentation give two idle periods for the same feature. The difference is 45 minutes of a GPU you are paying for by the minute: on an L4 at $0.8 an hour that is 60 cents per idle stretch, on an H200 at $5 an hour it is $3.75. Check the Settings page of your own endpoint rather than either page.
Both pages were live when we read them. This site has not asked Hugging Face which figure is current, and does not know.
Step one: the licence on the weights
- The GPU costs the same whatever runs on it, so the first read is the model's licence. Mistral's open-weight models are Apache 2.0 for research and individual use; commercial deployments require a Mistral license with separate terms for derivatives and production, and you can self-host them anywhere.
- Every model card on Hugging Face carries its own licence line, and the catalog does not read it for you. If the output will be sold, that line decides before the first minute is billed.
Path A: in the browser, from the Catalog
- Inference Endpoints needs a card on file in billing settings. Open the Inference Endpoints UI, click Catalog, filter by name, task and hardware price.
- The guide deploys meta-llama/Llama-3.2-3B-Instruct on the recommended Nvidia L4, keeping every pre-selected option. Create Endpoint; initialising takes about 3 to 5 minutes.
- The Overview tab shows the Endpoint URL; the Playground tab tests the model and gives a code snippet you paste an access token into. Endpoints are private by default, every request authenticated and encrypted in transit.
- Afterwards: pause it, delete it, or leave it and it scales to zero on its own, on a clock discussed below.
Path B: one command on Together
tg beta endpoints deploy google/gemma-4-E4B-it --endpoint quickstart-endpoint
- It creates an endpoint, attaches a deployment on the model's default hardware, routes all traffic to it, and prints the endpoint string as project-slug/quickstart-endpoint. First-time provisioning takes about 5 to 10 minutes for a model that size;
tg beta endpoints getwith the deployment id reports ready. - The console does the same from Endpoints, New endpoint: name, deployment name, model, quantization, hardware, region, min and max replicas, both defaulting to 1.
Pointing your tools at it
- Together: base URL api-inference.together.ai/v1, the endpoint string as the
modelparameter of the ordinary chat completions call, the same messages andmax_tokens. Prototype on serverless, move to dedicated without changing application code. - Hugging Face: the Playground snippet does the same for the Endpoint URL with your token.
- Run the day's job: the batch of documents, the evaluation set, the internal tool.
The day by the minute
- Inference Endpoints, per hour, billed by the minute, charged while initialising and while running: Nvidia T4 $0.5, L4 $0.8, A10G $1, L40S $1.8, A100 80 GB $2.5, H200 $5; CPU instances from $0.033. Hourly rate times hours times minimum replicas: $6.40 for an eight-hour day on the L4, $20 on an A100.
- Together, per minute per running replica: H100 $3.99 on demand or $1.99 preemptible, H200 $5.99, B200 $8.99. fal rents an H100 for your own deployments from $1.89 an hour.
- The AI job cost calculator multiplies any of these by the hours you type.
FIG 1LOG SCALE
One GPU for one month, at the published hourly rate times 730 hours
Each bar is the provider's on-demand hourly price multiplied by 730, the hours in an average month, for a machine left running the whole time. Idle hours cost the same as busy ones. Log scale, because the T4 and the eight A100s are fifty times apart.
1001,00010,000100,000
The month in hours
The chart above multiplies each hourly rate by 730. Hugging Face's small T4 at $0.40 an hour is $292; an Inference Endpoints L4 $584. fal's H100 $1,380, Together's preemptible H100 $1,453, on-demand H100 $2,913, B200 $6,563, and eight A100s on Hugging Face $14,600. Those are the prices of a GPU that never sleeps.
The same month, in tokens
- Mistral Large: $0.5 per million tokens in and $1.5 out, batch at half price. $2,913 buys about 1.9 billion output tokens.
- Together serverless: DeepSeek V4 Flash $0.14 in and $0.28 out, MiniMax M3 $0.30 and $1.20, Kimi K3 $3.00 and $15.00.
- The drafting page has the hosted API price lists in full.
Stopping it, and the two idle clocks
- Together: a deployment runs until you stop it. Stop, in the console or by setting min and max replicas to 0, scales it to zero and releases the hardware; in STOPPED it is neither billing nor serving, and Start brings it back. Deletion is permanent and ordered: stop the deployment, delete it, then the endpoint. The quick start's last step is
tg beta endpoints rmwith--force. - Hugging Face, two pages, two idle periods: the quick start says the endpoint scales down to zero after 1 hour of inactivity; the autoscaling guide says an endpoint with no requests for over 15 minutes is scaled to 0 replicas. The contradiction block above shows both. The 45 minutes between them is 60 cents on an L4 and $3.75 on an H200, per idle stretch.
- The price of zero: a new request triggers a cold start whose length depends on the model's size, the server answers 502 Bad Gateway while the replica initialises, and there is no request queue, so your client must retry. Check the Settings page of your own endpoint for the period actually applied, then pause by hand when the day is done.
The clauses that bite a small team
- Together: pay as you go with non-refundable fees; credits funded by ACH or wire are not usable until they clear; access can be suspended on notice if any amount is 5 days past due; you may not terminate the agreement without Together's written consent.
- Hetzner, for a dedicated box without a GPU: AX42-1 at EUR 97.30 a month plus a one-off EUR 49.00 setup fee, net of 19% VAT for German customers; backups are the customer's duty and there is no claim to a particular IP address.
What leaves with you
- Mistral's open weights can be self-hosted anywhere, so a workflow built on them does not depend on any one host at any one price.
- Hugging Face says you own the Content you create and will not sell it.
- DigitalOcean: snapshots and backups cannot be downloaded off the platform; getting data out means copying it yourself with rsync or SFTP. Keep the weights, the system prompts and the data on a disk you control.
What ends it
- Hugging Face reserves the right to suspend or terminate access at any time, with or without cause, with or without notice, and may remove your Content at its sole discretion.
- Together's agreement cannot be ended by you without its written consent.
- DigitalOcean can terminate access at any time, effective immediately, and deletes Services Content on termination.
- The answer is the same as for the support bot: keep the pieces in your own folder and know the second host's deploy command.
What to do today
- Put a card on file, deploy the catalog's Llama 3.2 3B on an L4 with the defaults, and run one real job through the Endpoint URL from the Playground snippet.
- Note the minutes on the billing page, then pause it.
- Write down your team's real token volume for the month. Against $584 to $2,913, it is the only figure on this page that decides anything.
Cite this page
Earns.io (2026). A GPU That Never Sleeps Costs $584 to $2,913 a Month. The API Sells the Same Month for a Fraction, Until You Pass a Billion Tokens. Figures checked 2026-09-14. Retrieved from https://earns.io/en/methods/running-your-own-model
https://earns.io/en/methods/running-your-own-model
Mistral AI
mistral.ai
European model maker with a per-token API and open-weight models you can self-host under Apache 2.0 for research and individual use.
Official site
This link pays this site nothing today. It goes to mistral.ai.
- 20 published
- 0 not published
- 1 given two ways
Hugging Face
huggingface.co
Hub for open models, datasets and hosted demo apps; free to use, $9 a month for PRO, GPU hardware billed by the hour.
Official site
This link pays this site nothing today. It goes to huggingface.co.
- 20 published
- 0 not published
- 1 given two ways
Together AI
together.ai
Serverless inference and GPU rental for open models, priced per million tokens or per GPU hour; you own your inputs and outputs.
Official site
This link pays this site nothing today. It goes to together.ai.
- 20 published
- 0 not published
- 1 given two ways
fal.ai
fal.ai
Image, video and audio model APIs billed per output on prepaid credits that expire after 365 days; free promotional credits expire in 90.
Official site
This link pays this site nothing today. It goes to fal.ai.
- 20 published
- 0 not published
- 1 given two ways
Hetzner
hetzner.com
Servers and hosting billed by the hour, cheap and unmanaged.
Official site
This link pays this site nothing today. It goes to hetzner.com.
- 20 published
- 0 not published
- 1 given two ways
DigitalOcean
digitalocean.com
Cloud servers and managed app hosting.
Official site
This link pays this site nothing today. It goes to digitalocean.com.
- 20 published
- 0 not published
- 1 given two ways